
Data Annotation / Language, Speech & Document AI
Text, Audio & Document Data
Multimodal annotation for language, speech and document AI: text classification and entity labeling, audio segmentation and transcription, and region-level labeling for structured document extraction. One quality framework covers visual, language, audio and document workflows.
MULTIMODAL LABELSDECODING / BITS
Data Annotation
Project overview
What we built.
A concise view of the documented implementation and features shipped.
Scope clarification: Examples are taken from the Decoding Bits Data Services portfolio. Client names and datasets are not disclosed.
- Text classification and categorization
- Named entity recognition and entity labeling
- Intent and sentiment annotation
- Content and attribute-based labeling
- Audio classification and sound events
- Speech segmentation and speaker identification
- Timestamp labeling and transcription
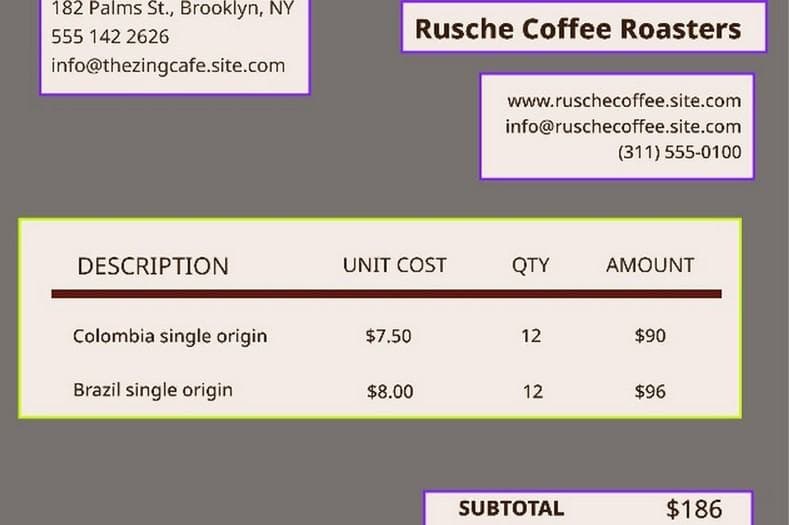
- Region-level labeling and structured extraction for documents
- QC for missing labels, category consistency, timestamps and speaker errors
Implementation
Annotation techniques.
Techniques documented in the Decoding Bits Data Services portfolio for this type of work.
Portfolio examples
Annotation examples.
Illustrative examples from the Decoding Bits Data Services portfolio.
Document / structured visual data
More work
Explore other builds.
Related projects drawn from the approved portfolio.
Build something with us.
Have a similar AI, automation or software challenge?